The Agent Can See Your App. How Often Can It Look?
AI coding agents can now interact with mobile apps, but their effectiveness depends on iteration speed. This blog explores how React Native architecture influences feedback loops and AI-driven developer productivity.
The question about AI coding agents on mobile used to be whether one
could even drive your app. That question is increasingly settled. The
one that now determines how useful an agent can be is how quickly it
gets to try, observe the result, and try again. In React
Native, that
number depends heavily on whether a change can stay inside the
JavaScript feedback loop or requires rebuilding the native
app.
JavaScript vs Native Feedback Loops in React Native
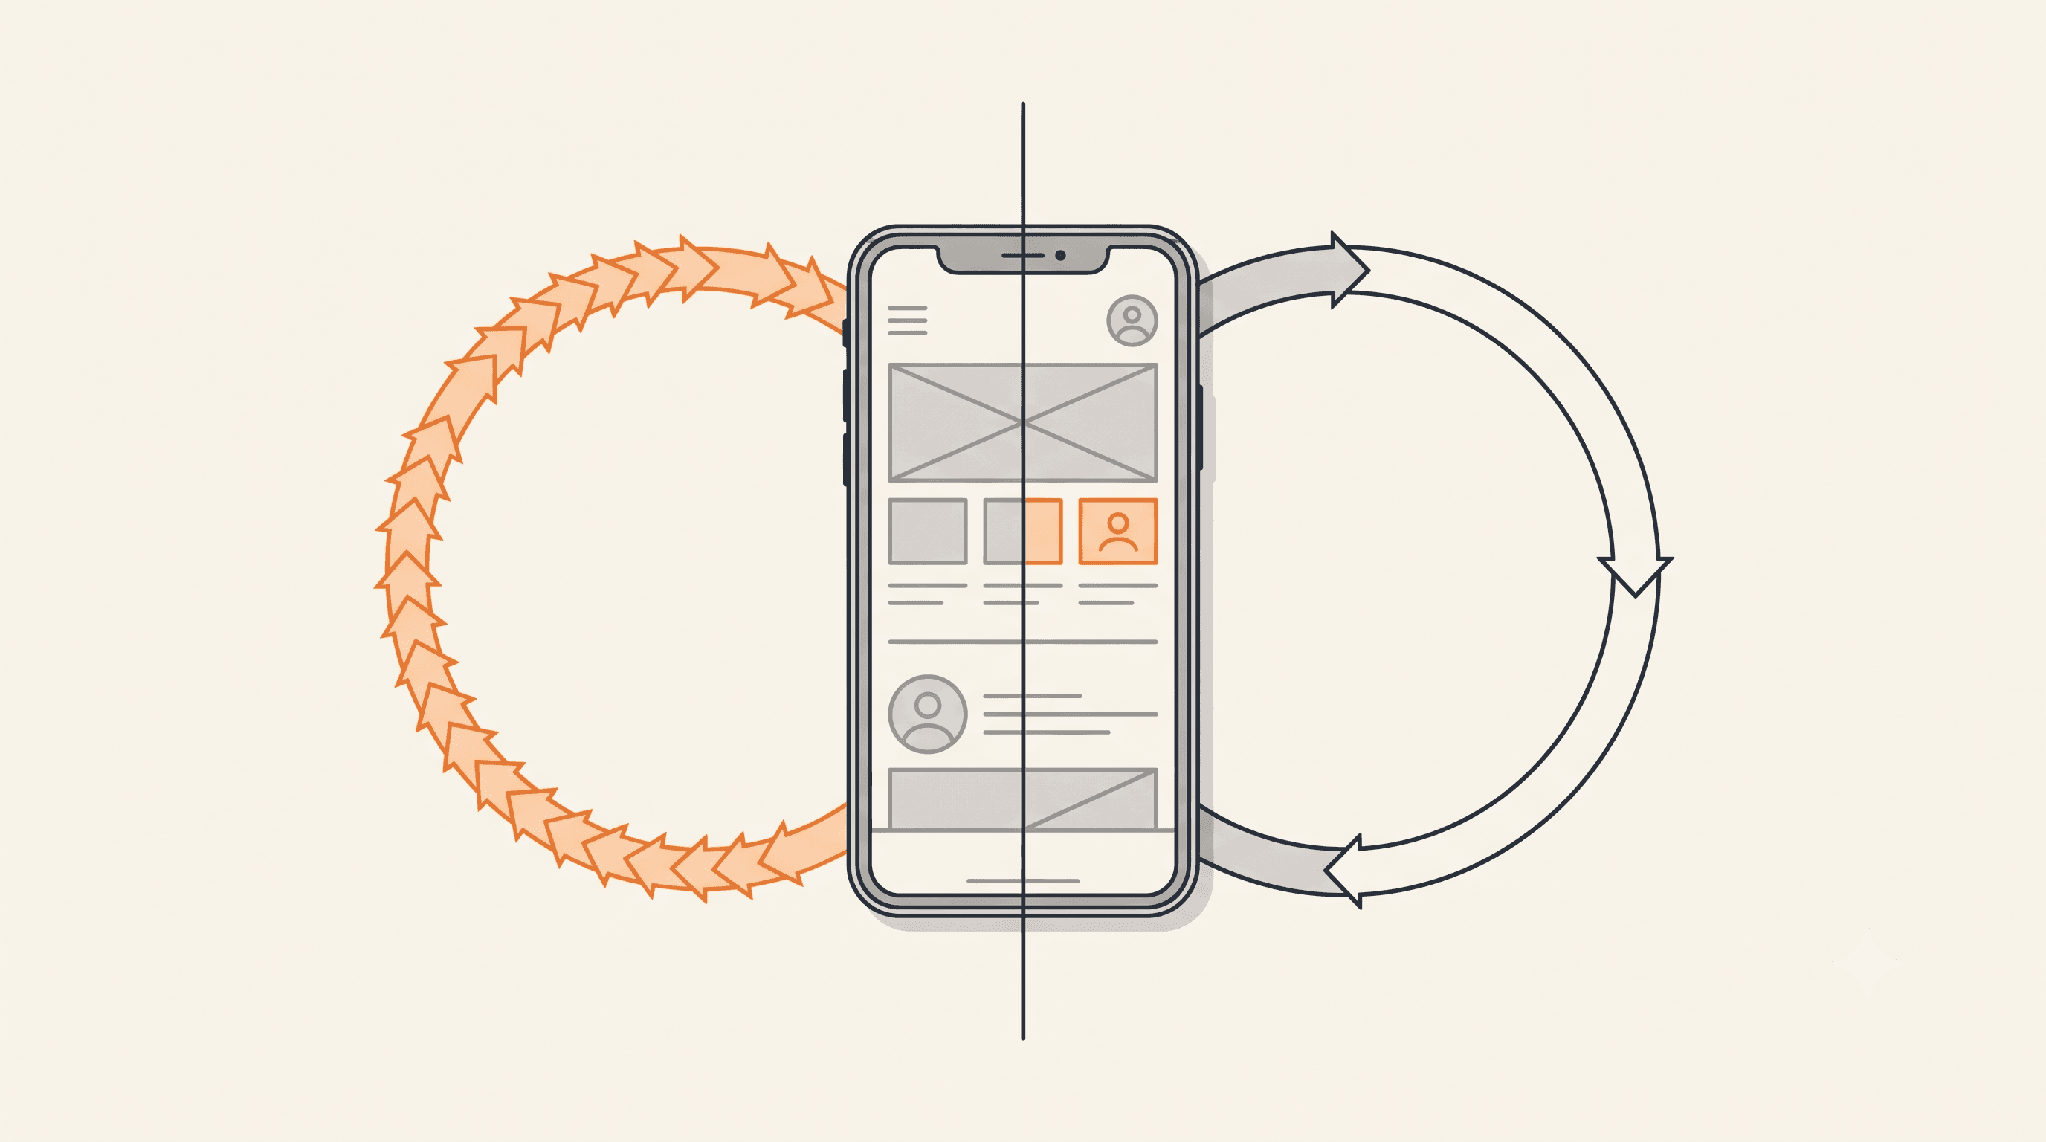
The same app, two feedback loops: fast for JavaScript-only iteration,
slower when a change requires rebuilding the native app.
We keep seeing the same scene. A team wires a coding agent into its
React Native repo, expects the numbers everyone's been quoting, and the
agent writes reasonable code, but the whole thing feels flat next to
what the web team is getting. The easy read is that agents just aren't
good at mobile yet.
That read misses a major part of the problem, and it can be an expensive
miss because it talks teams out of fixing something they can actually
influence.
The capability gap has closed
For most of the last two years there was a real gap. An agent could
write mobile code but had limited ability to see what happened next. It
couldn't easily boot a simulator, tap a button, read a native crash, or
notice a keyboard sitting on top of the submit field. On the web, much
of that loop was already straightforward: start a dev server, hit a URL,
inspect the page, and read the console. Mobile agents had far less
visibility.
That gap has narrowed dramatically.
On iOS, getsentry/XcodeBuildMCP gives an agent access to builds,
simulators, log capture, debugging, screenshots, and snapshot_ui, which
exposes the on-screen view hierarchy with element references that can be
used for interaction. On Android, ADB-based tooling provides similar
capabilities, while mobile-next/mobile-mcp supports both platforms
through accessibility-driven snapshots and device interaction.
metro-mcp connects to a running React Native
app
through the Chrome DevTools Protocol for runtime, component, and network
inspection. Callstack has published React Native conventions written
specifically for AI
agents,
and tools such as SootSim are also targeting faster React Native
development and agent-driven feedback loops.
So the agent can increasingly see your app. The more useful question now
is how quickly it can act on what it sees.
The number that actually decides this
Agentic coding works because of a loop: generate, run it, look, fix, and
go again. What that loop is worth depends on how cheaply the agent can
get through each iteration.
On the web, application feedback after many common edits can arrive
almost immediately. In React Native, the feedback time depends heavily
on the kind of change being made.
The ranges below are illustrative rather than benchmarks. Exact times
vary by project size, hardware, build configuration, caching,
dependencies, and development environment. That variation is also why
the last section asks you to measure your own.
| Change type | Feedback loop |
|---|---|
| JavaScript only — Metro Fast Refresh, state preserved | about a second |
| Incremental native rebuild | 30 seconds – 1 minute |
| Cold native build | 2 – 5 minutes, often longer |
That can leave a large gap between JavaScript-only iteration and a
change that requires recompiling the native application.
The important dividing line isn't whether your JavaScript uses native
functionality. React Native applications do that constantly without
requiring a rebuild. The slower path appears when an edit changes native
source code, native dependencies, generated native code, or build
configuration in a way that requires the native binary to be rebuilt or
reinstalled.
That distinction matters.
A JavaScript change that Fast Refresh can apply may become visible
almost immediately. A native change that requires compilation may take
tens of seconds or minutes before the agent can observe the result.
The JavaScript-to-native architecture line used to be primarily a
portability and performance decision. In an agent-assisted workflow, it
can also become an iteration-speed decision.
Why the loop cost sets the ceiling, not the model
An agent gets through a real task by trying, checking, and correcting.
Give it one shot and it has to get the thing right immediately. Give it
repeated opportunities to inspect the result and make corrections, and
it has room to recover.
Cheap iteration is one of the things that pushed agentic coding beyond
autocomplete.
So feedback-loop cost isn't an ergonomic footnote. It affects how many
experiments an agent can make within the same amount of engineering
time.
Reducing the cost of an iteration doesn't translate neatly into a fixed
multiple of output. In some cases, faster feedback can make a category
of task practical that previously required too much waiting between
attempts.
Same agent. Same model. Same engineer. Different feedback loop.
In our experience, teams can budget mobile AI work as if the iteration
pattern will match what they see on the web. Often it won't, and part of
the reason is architectural rather than a question of choosing a better
model.
The obvious pushback is to run multiple agents in parallel and let
throughput hide the latency. Parallelism can help, but it doesn't remove
the underlying cost of an individual feedback cycle.
Shared build infrastructure can also become a bottleneck as more agents
request native builds, simulators, or test environments at the same
time. Additional agents give you more concurrent attempts, but they
don't automatically make each native-touching attempt cheaper.
The native boundary is a velocity budget
Once a native rebuild takes substantially longer than a JavaScript
refresh, "let's just add a small native change" becomes an
iteration-speed decision that teams may not have priced into the
development loop.
A few habits follow from that:
Reach for JavaScript first, and stay there until native code
genuinely provides something you need. The decision should still be
based on product requirements, platform capabilities, performance,
and maintainability, but iteration cost now belongs in that
calculation too.Batch related native changes where practical instead of dripping
them in. Every native-touching edit that requires recompilation
incurs the slower feedback cycle again.Treat a new native API or dependency as a planned architectural
decision, rather than something that slips into a routine ticket
without considering its development and build implications.Settle native boundaries deliberately. Teams already do versions of
this for maintainability and build speed, keeping appropriate
product logic in JavaScript and using tools such as Expo Prebuild to
generate and manage native projects rather than hand-editing every
native configuration. Prebuild doesn't remove the need for native
rebuilds when native dependencies or configuration change, but it
can make that boundary easier to manage.
None of this is anti-native. Some capabilities genuinely belong in
native code.
The narrower point is that the amount of native surface you change, and
how frequently those changes require recompilation, can have a direct
and measurable effect on how quickly agents receive feedback.
That cost was easier to ignore when a developer was making a handful of
deliberate iterations. Agents make iteration count much more visible.
In fairness, native-build time is also a moving target. Precompiled
frameworks, configuration caching, compiler caching, and better build
tooling continue to reduce it.
But making the slower side faster does not eliminate the difference
between a Fast Refresh and a native rebuild. For agent-assisted
development,
the ratio between those feedback paths is worth measuring.
An agent navigates by labels, not by pixels
A fast loop is necessary, but it isn't enough on its own. The agent
still has to find things on the screen, and that depends partly on how
well your UI describes itself.
Tools that expose an accessibility or UI hierarchy can give an agent
structured references to elements on the screen. But an element without
useful text, roles, identifiers, or accessibility information may
provide the agent with very little semantic context.
The agent can be looking at the right screen and still struggle to
determine which element it should interact with. It may then fall back
to less reliable approaches such as screenshot coordinates.
Every failed identification wastes another inspection and interaction
cycle. If the task already includes slower native rebuilds, those
additional mistakes compound an already expensive loop.
So here's the reframe.
testID and accessibility metadata aren't interchangeable, and
accessibility labels should still be designed first for the people who
depend on them. But together, well-structured identifiers, roles,
labels, and semantic UI information also make an application easier for
automated tools and agents to navigate.
The work teams do to make interfaces addressable turns out to benefit
agent tooling too.
Two more cheap wins fall out of the same idea:
Deterministic launch states. Six taps to reach a bug are six
opportunities for the workflow to go off course on every cycle. A
deep link, test fixture, or debug launcher that drops the app
directly into a known state can reduce that setup cost dramatically.Typed native boundaries. An agent has more structure to reason
about when working with a well-specified TurboModule and generated
interfaces. Give it a hand-rolled bridge built around loosely
structured payloads and there are fewer guarantees for both the
agent and the developer to rely on. The New
Architecture
has an additional benefit here: its typed contracts make the
JavaScript-native boundary easier to inspect and reason about.
What The Loop Still Can't Do
A screenshot proves something rendered. It says nothing about whether
the app is any good.
Closing more of the execution loop doesn't remove the human. It changes
where human judgment matters most.
A simulator can hide the things that actually damage a mobile
experience: dropped frames under realistic load, thermal throttling as
the device heats up, physical-device performance, haptics, hardware
behavior, and keyboard interactions that don't behave exactly as
expected.
Passing in a simulator and passing on a device are two different claims.
Any honest workflow keeps a person involved where product judgment and
real-device validation matter.
It's also worth pricing the harness honestly.
XcodeBuildMCP plus an Android automation layer plus metro-mcp, with the
right workflows enabled, session defaults configured, simulators
available, and code signing sorted for real devices, still requires
setup and maintenance.
Available doesn't mean zero-cost to operationalize.
The investment may be modest compared with the engineering work it
enables, but it is still part of the cost of running an agent-assisted
mobile
development
environment.
What To Measure This Week
The argument here ultimately comes down to numbers you can produce on
your own codebase in an afternoon.
Measure them before putting a budget behind any mobile AI plan.
Instrument the feedback loop. On one representative screen, run
an agent through a JavaScript-only change and a change that requires
a native rebuild. Measure both the edit-to-observable-result latency
and the total end-to-end time required for the agent to inspect and
respond.Find the cliff on your own codebase. Compare JavaScript-only
feedback with native-rebuild feedback. That ratio is one of the
factors determining how much useful iteration an agent can complete
in a given period.Test addressability. Compare similar tasks on screens with clear
semantic labels and stable test identifiers against screens where
elements are harder for automation to identify. Count the extra
inspection or interaction cycles.Test launch determinism. Add a deep link or debug route directly
to the target state and run the workflow again. Measure how much
repeated setup time disappears.
Agents are non-deterministic, so run each condition several times and
report a range rather than a single figure.
A range you actually measured is more useful than a generic benchmark,
and technical audiences will trust it more.
The Point For Leaders
Mobile isn't shut out of the gains you're seeing from AI-assisted
development on
the web.
But the size of those gains can be strongly influenced by architecture
choices that, on the surface, appear to have little to do with
AI.
And you can measure their effect before committing a larger budget.
When code generation becomes cheap, feedback and iteration become
increasingly important constraints. One valuable asset is therefore a
codebase that an agent can understand, execute, inspect, and move
through quickly.
You don't simply buy that capability. You design for it.
The teams that pull ahead will be the ones that start treating agent
iteration speed as another engineering characteristic of the system and
make those architecture decisions deliberately.
Sources
getsentry/XcodeBuildMCP
--- iOS build, simulator, log, debugger, screenshot, and snapshot_ui
tooling for agentsmobile-next/mobile-mcp
--- cross-platform (iOS + Android) mobile automation via
accessibility snapshotsmetro-mcp --- React Native runtime
inspection over the Chrome DevTools ProtocolSootSim --- browser-based React Native
simulator built to be driven by agentsCallstack --- Giving AI Agents Hands: Mobile Feedback Loops with
Agent
DeviceReact Native --- Build speed
documentation --- on
native build times, and Fast Refresh applying edits within a second
or twoCodex CLI for mobile development: iOS with XcodeBuildMCP, Android
CLI, and React
Native
--- background on the agent-driven mobile toolchain